Publications
 NeurIPS
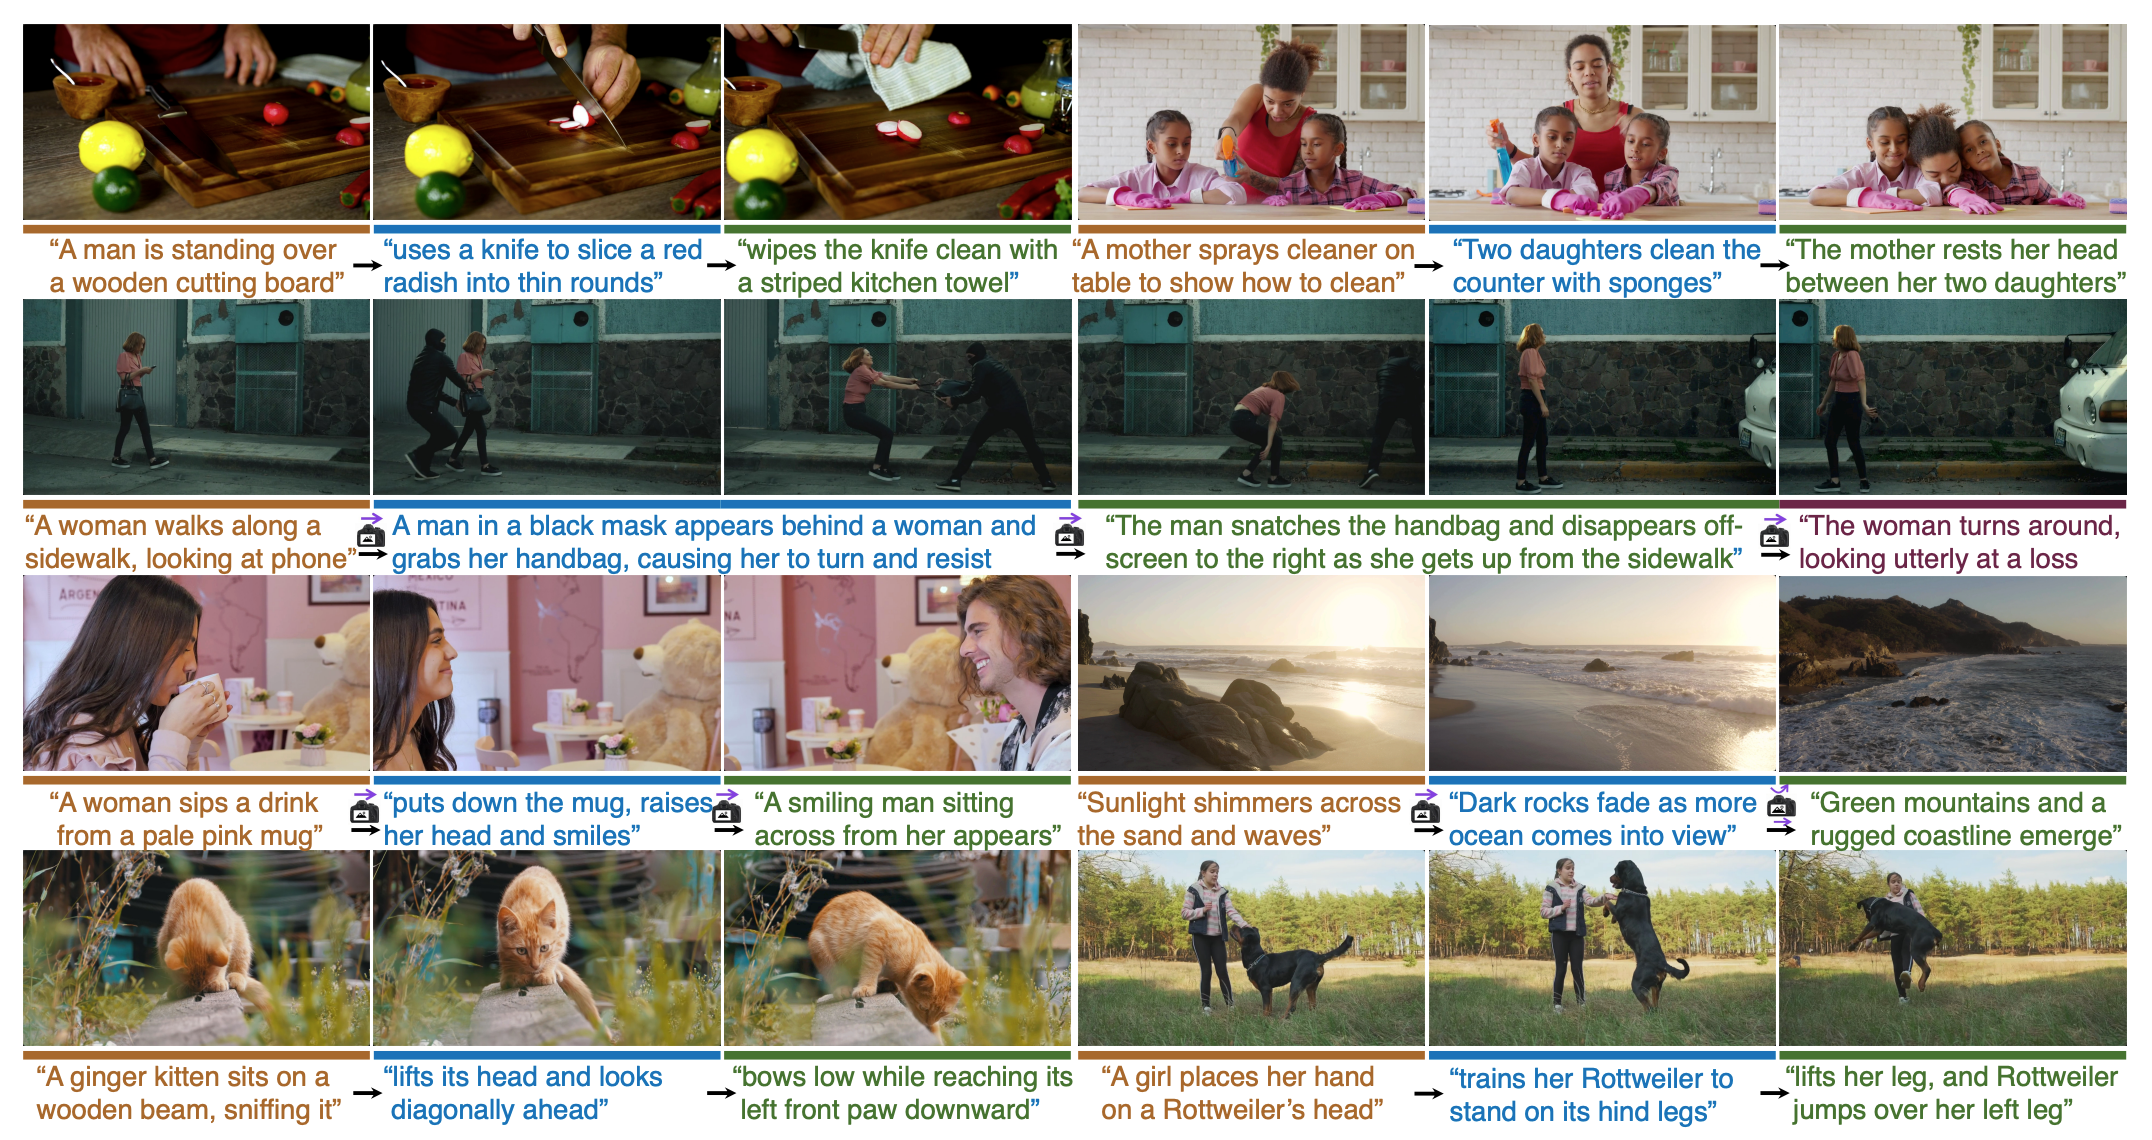
MEV: A Multi-Event Video Dataset for Long-Take Generation
Conference on Neural Information Processing Systems (NeurIPS), 2026.
"MEV is a multi-event video dataset for long-take video generation, providing real-world videos with precise temporal boundaries, fine-grained procedural annotations, and event-centric conditioning for more coherent multi-event generation."
 ECCV
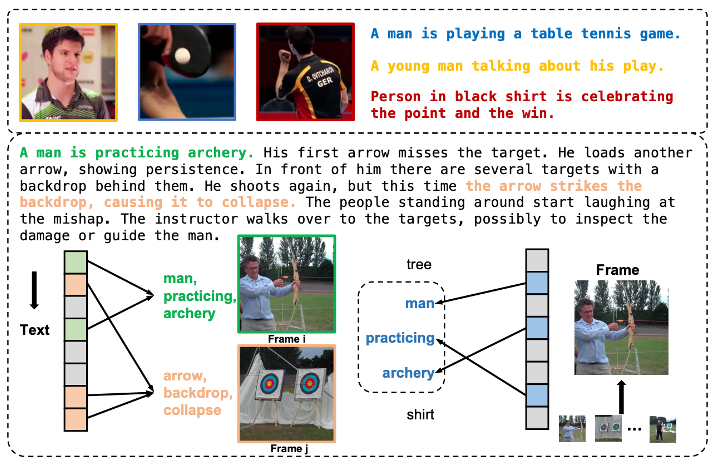
MoVA: Learning Asymmetric Dual Projections for Modular Long Video-Text Alignment
European Conference on Computer Vision (ECCV), 2026.
"MoVA learns dual asymmetric projections for long video-text alignment: a text-side projection adaptively selects frame-aware caption subspaces, while a video-side projection disentangles text-relevant visual concepts, preserving global cross-modal semantics and scaling naturally to long captions and videos."
 Submission
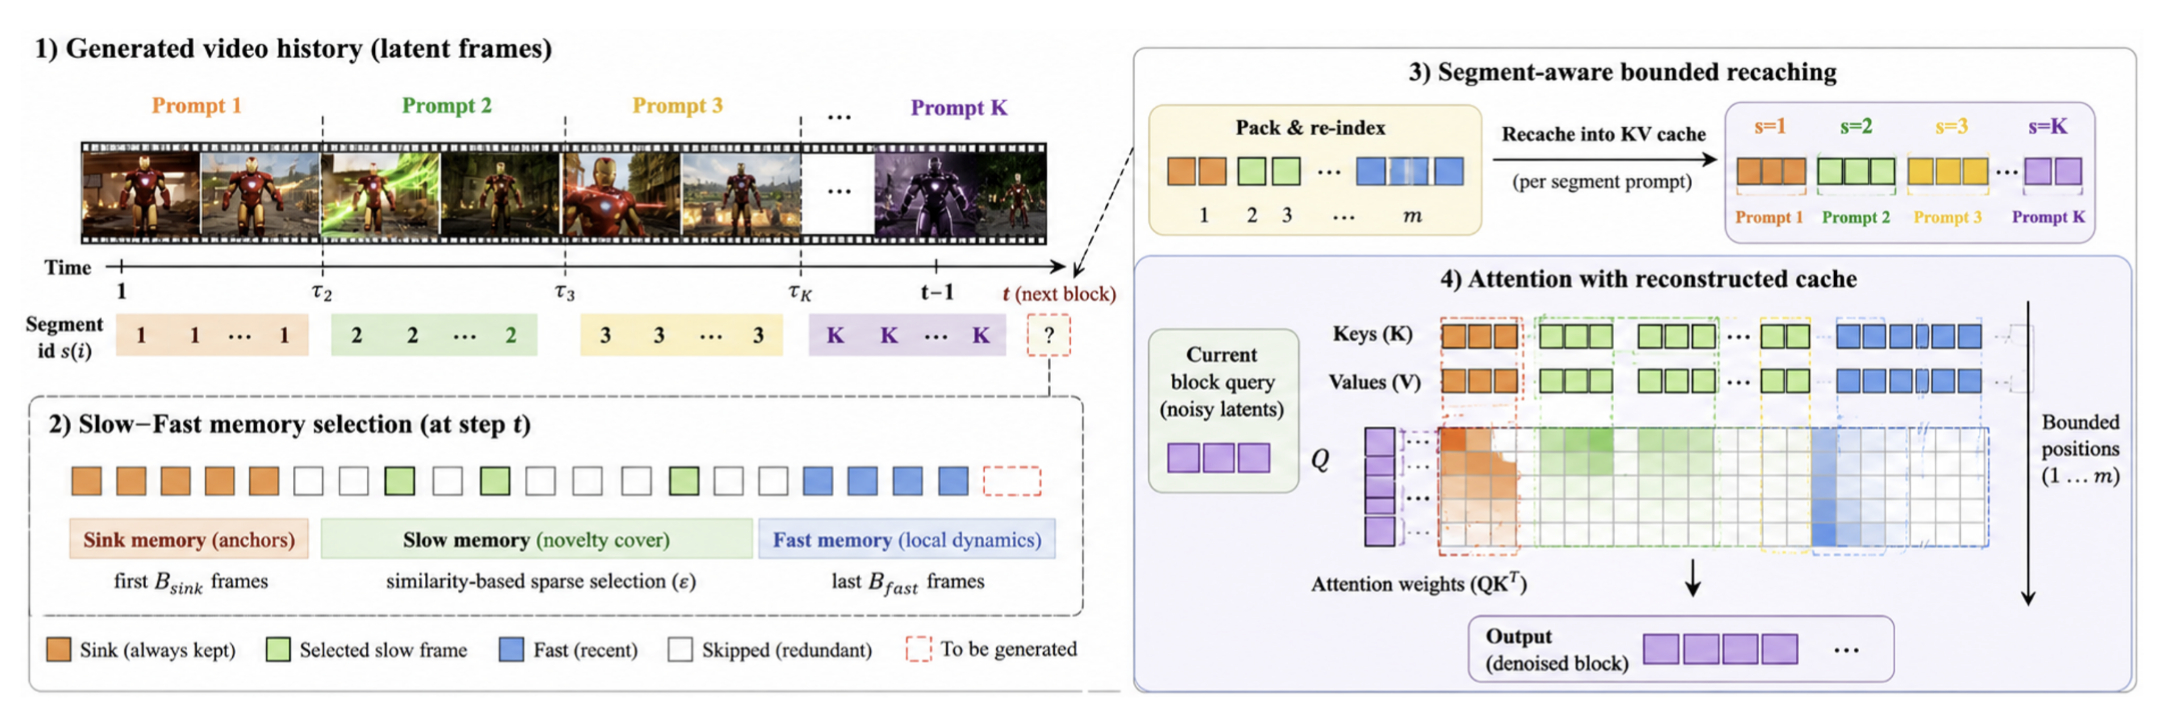
Event Forcing: Consistent Autoregressive Multi-Event Video Generation via Event-Level Test-Time Correction
Under submission, 2026.
"Event Forcing studies autoregressive multi-event video generation under accumulated temporal errors and event-level inconsistency. It introduces a test-time correction strategy that aligns generated event transitions with intended controls, improving long-horizon coherence without retraining the base model."
 Submission
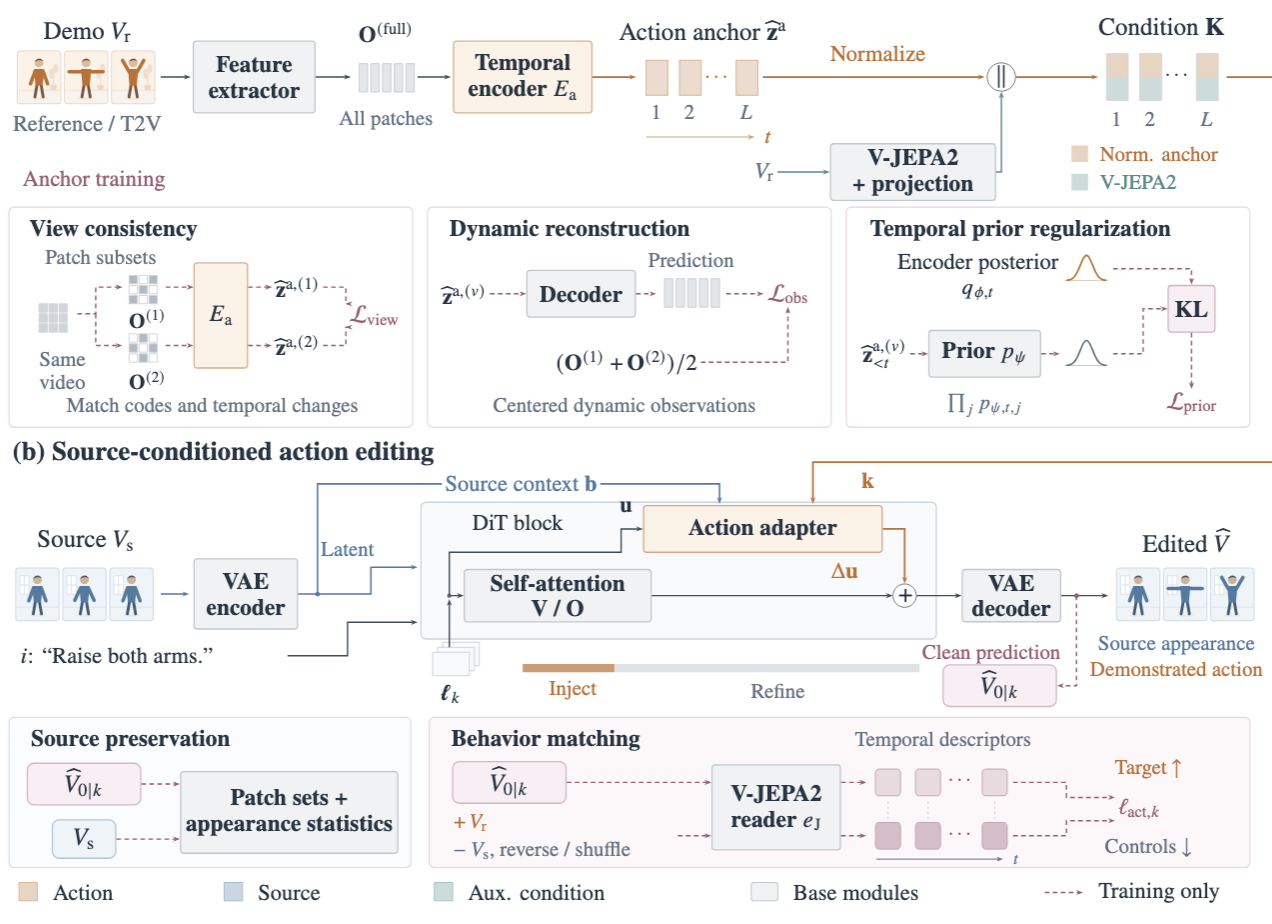
DAVE: Learning Dynamic Signals for Action-Centric Video Editing
Under submission, 2026.
"DAVE explores how a video can depict a new action while keeping its original subjects and setting. It extracts reusable motion cues from example clips, including generated ones, and uses them to guide changes in movement while limiting changes to unrelated visual details."
 Submission
Directional Residual Adaptation for Versatile Conditional Video Generation
Under submission, 2026.
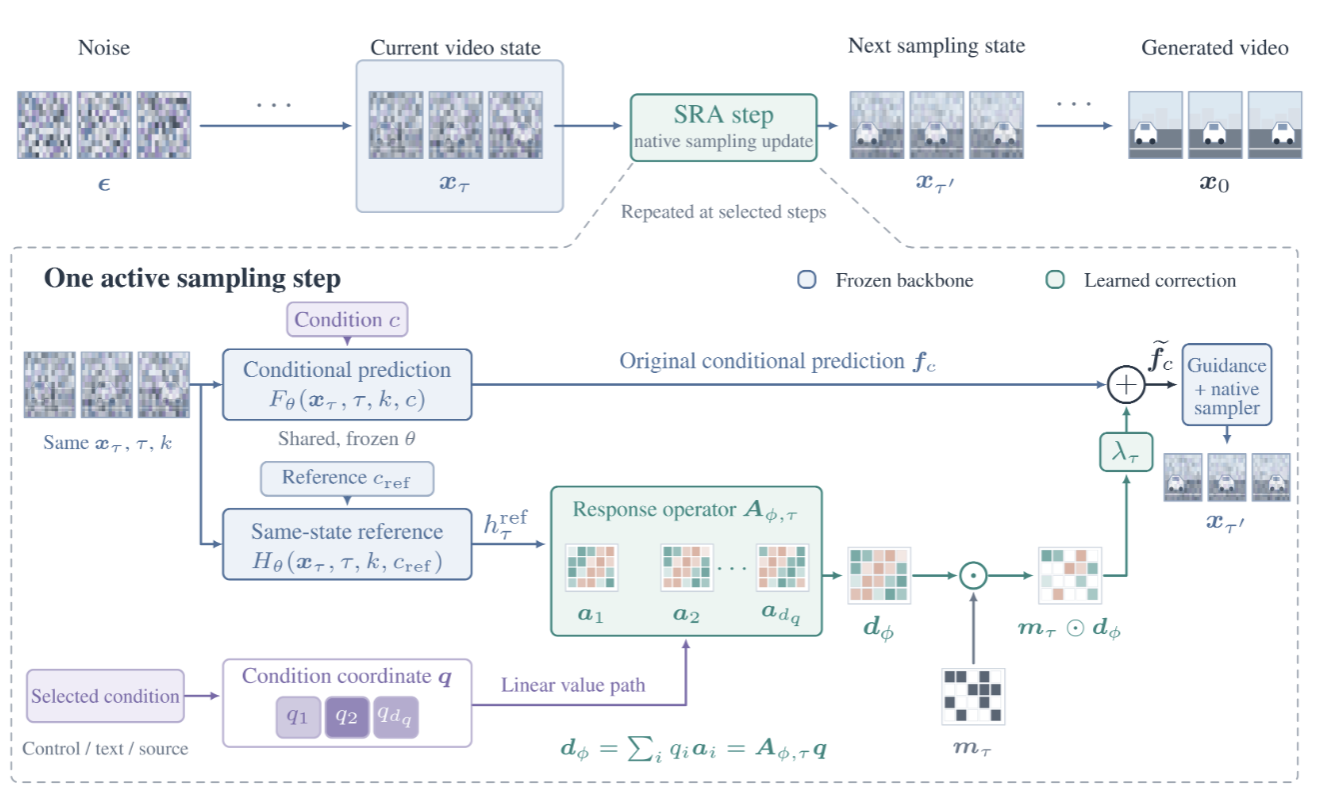
"This work steers video diffusion with an added correction that responds linearly to selected control inputs and adjusts its coefficients as sampling progresses. Applying this structure to the correction lets the underlying model retain its nonlinear behavior, supporting a range of conditional generation tasks."
 Submission
Prospective Forcing: Learning to Look Ahead for Autoregressive Long Video Diffusion
Under submission, 2026.
"Prospective Forcing gives an autoregressive video model practice anticipating several steps ahead. Parallel prediction heads make the stored history useful beyond the next chunk, while a verifier screens candidate continuations during sampling and falls back to ordinary generation when needed. Accepted proposals let the model bypass repeated backbone passes."
 ICLR
Controllable Video Generation with Provable Disentanglement
International Conference on Learning Representations (ICLR), 2026.
"CoVoGAN is a controllable video generation framework that disentangles static and dynamic concepts for independent control, achieving superior quality and controllability through theoretically grounded latent dynamics modeling."
 Preprint
An Empirical Comparative Study of Classical Dimensionality Reduction Methods: MDS, Isomap, and LLE
Preprints, 2025.
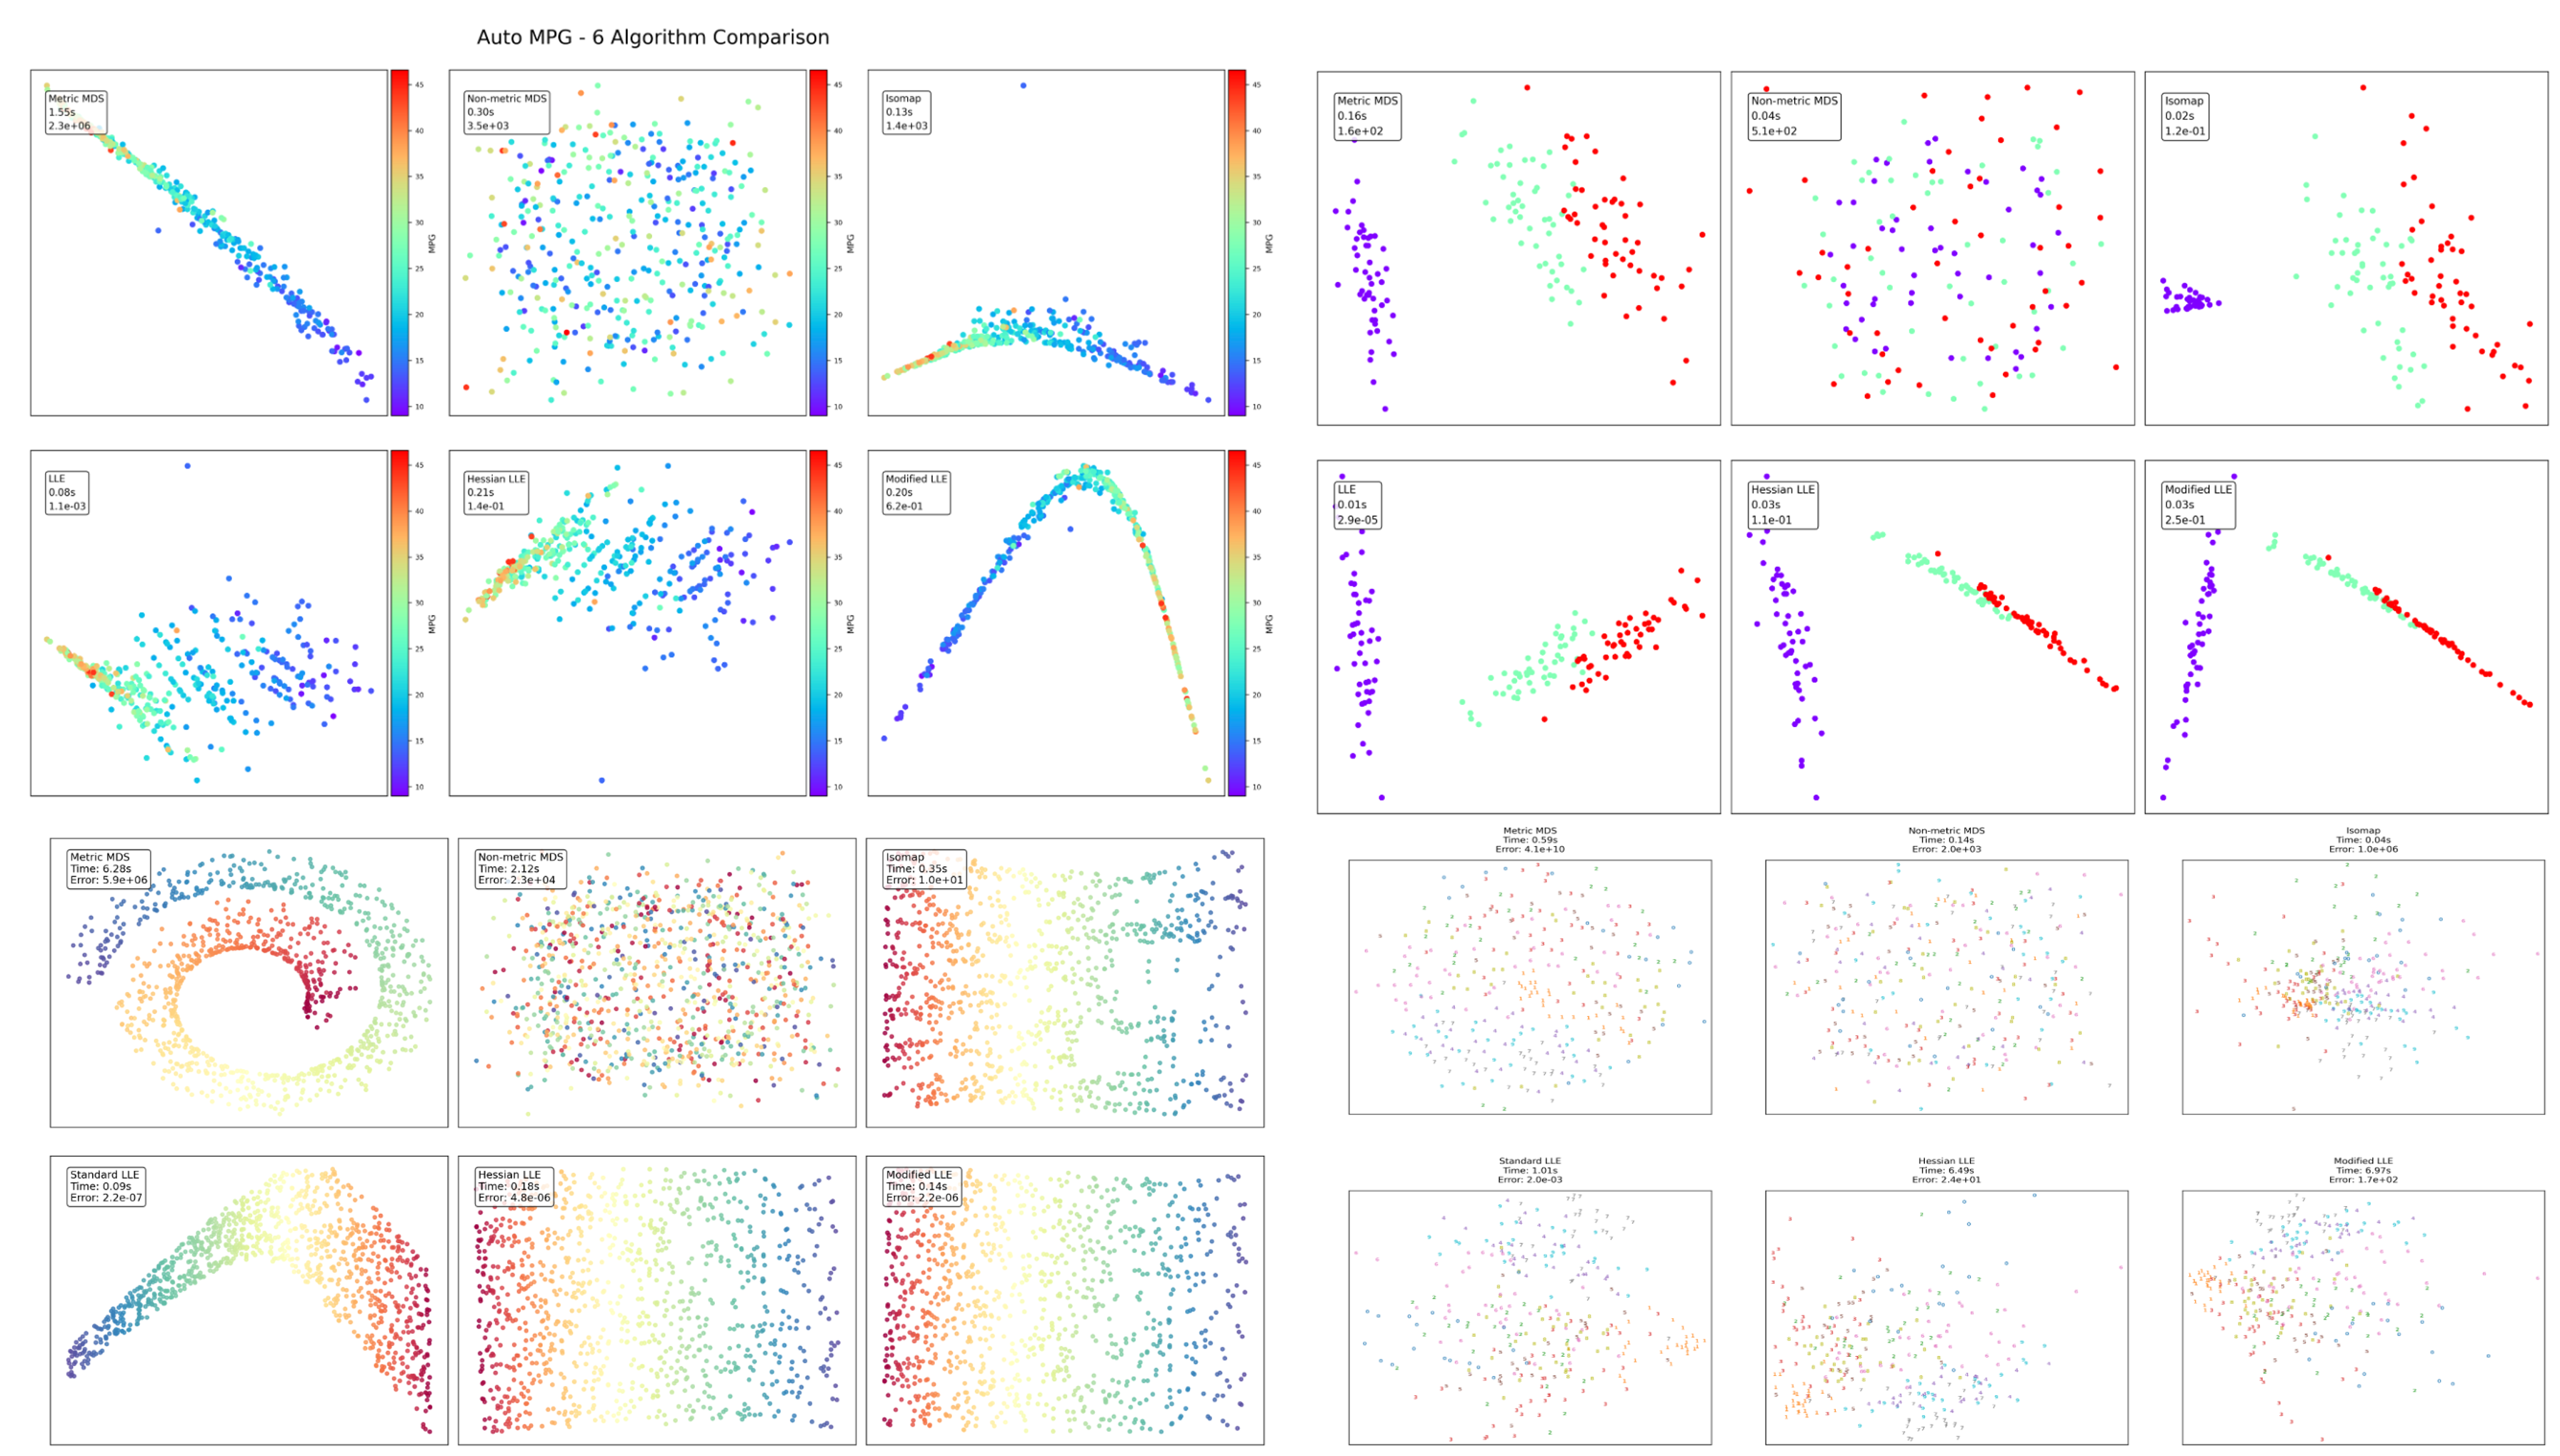
"This work systematically compares MDS, Isomap, LLE, and their variants across synthetic and real-world datasets. It analyzes reconstruction error, runtime, and structural preservation to clarify when each classical dimensionality reduction method is most practical."
 NeurIPS
CausalVerse: Benchmarking Causal Representation Learning with Configurable High-Fidelity Simulations
Conference on Neural Information Processing Systems (NeurIPS), 2025. Spotlight
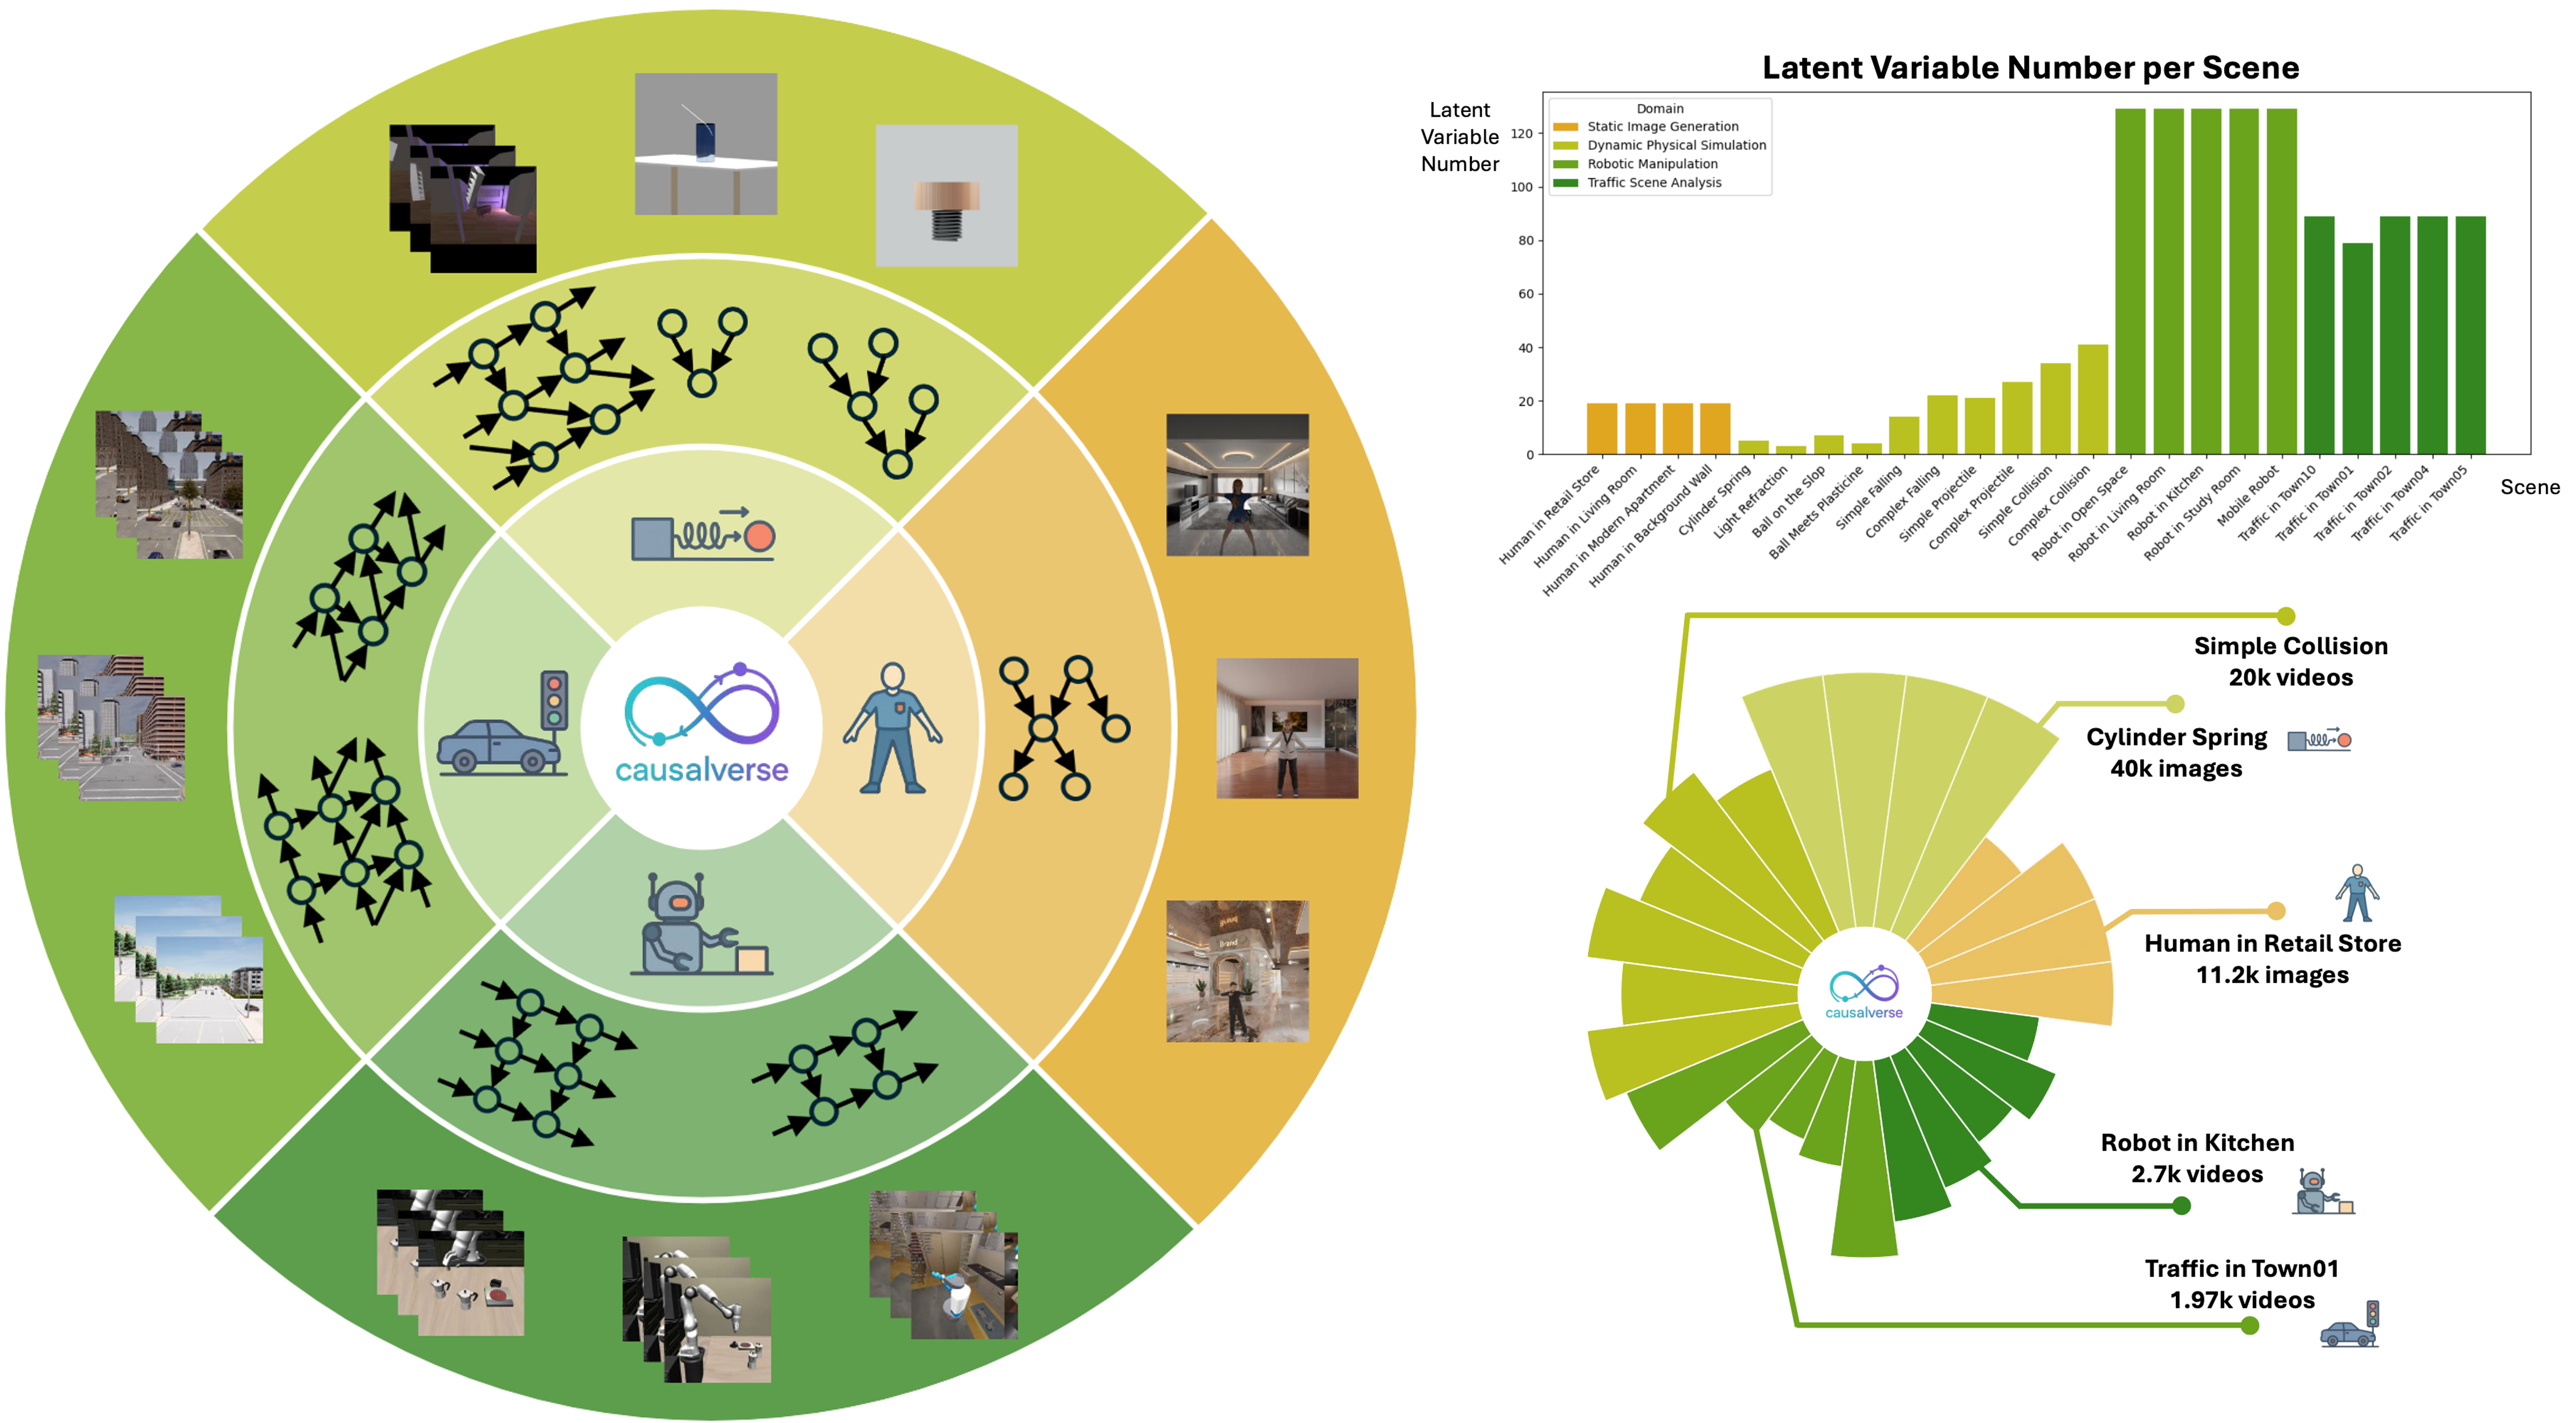
"CausalVerse is a high-fidelity visual benchmark for Causal Representation Learning, offering ground-truth causal structures across diverse static and dynamic scenarios to enable rigorous and realistic evaluation of CRL methods."
 TITS
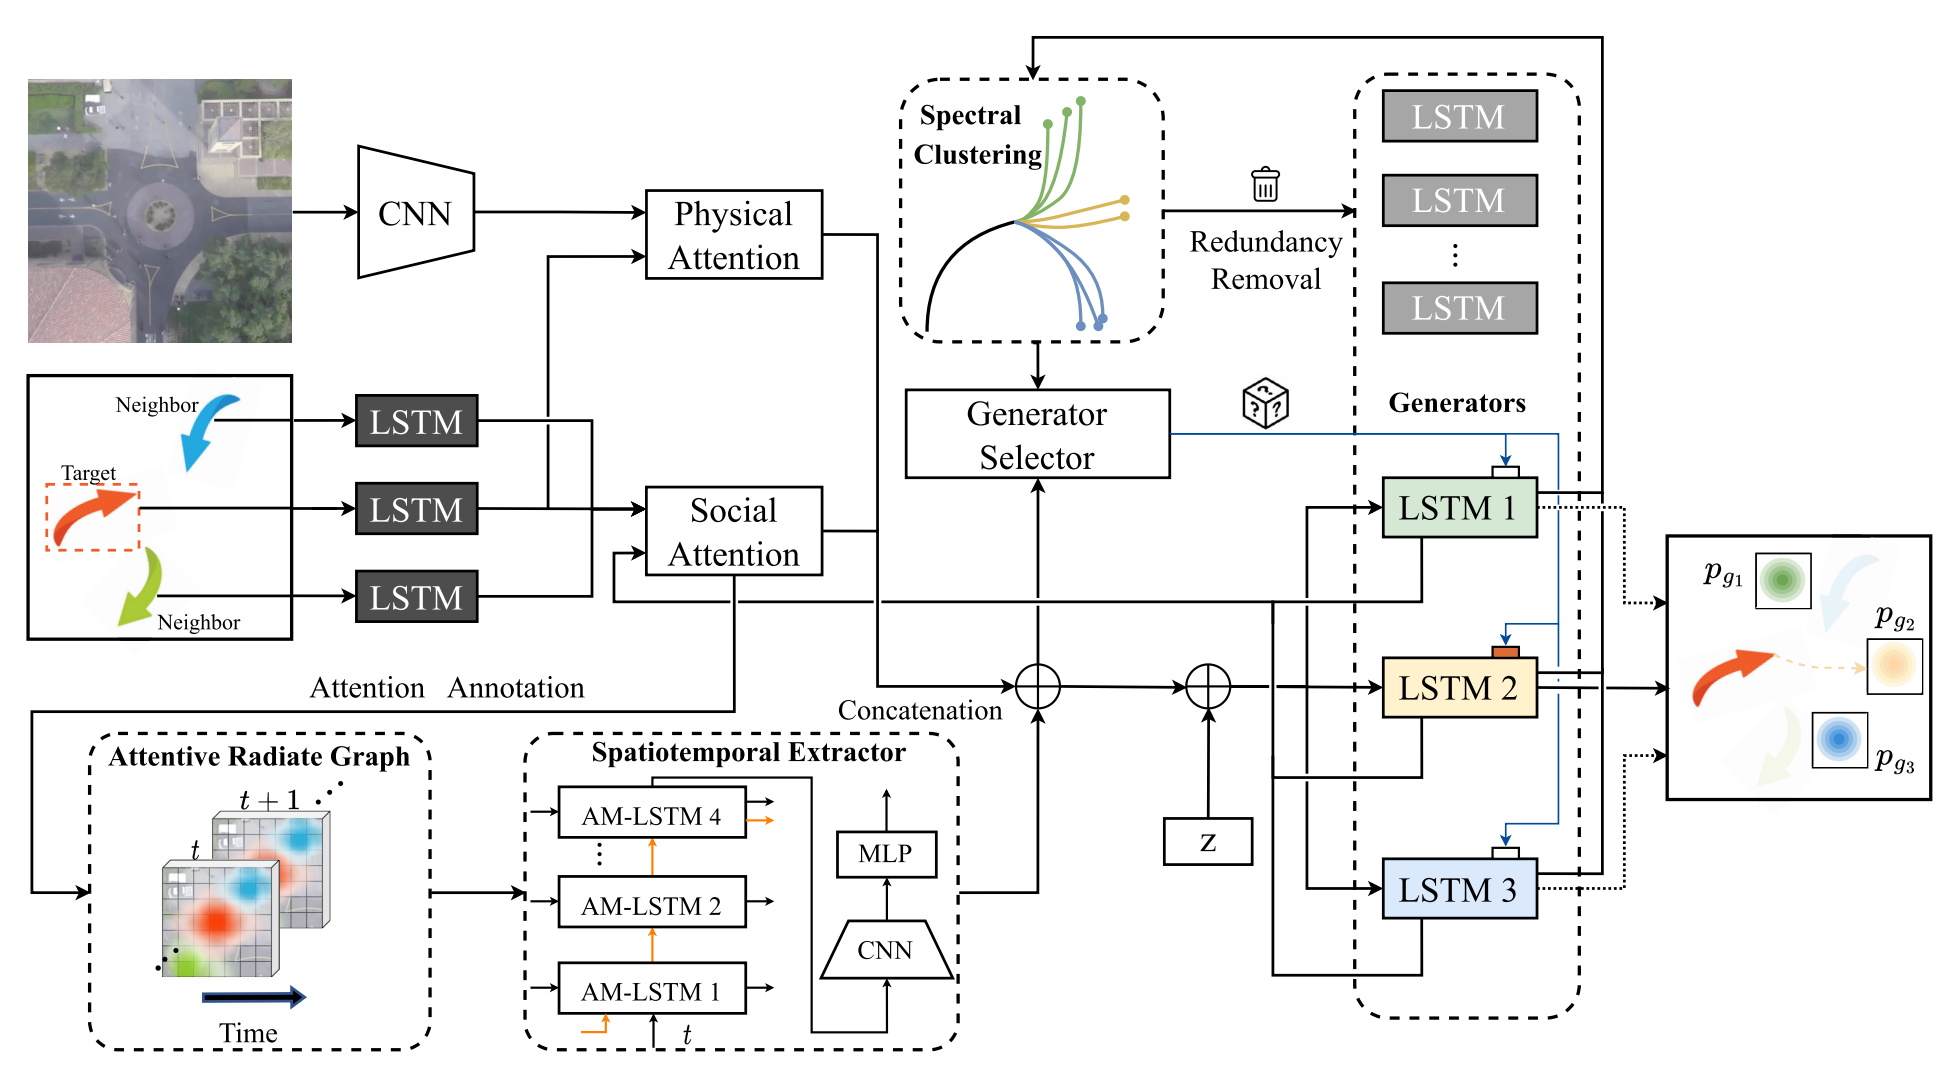
Attentive Radiate Graph for Pedestrian Trajectory Prediction in Disconnected Manifolds
IEEE Transactions on Intelligent Transportation Systems (TITS), 2025.
"The problem of multimodal pedestrian prediction in disconnected manifolds is considered. A graph-based generative method that incorporates the localized influence radiating from pedestrian movements is proposed and implemented on GPU."
 FG
BEAVP: A Bidirectional Enhanced Adversarial Model for Video Prediction
IEEE International Conference on Automatic Face and Gesture Recognition (FG), 2024.
"BEAVP, a stochastic video prediction model based on coupled GANs, leverages cycle-consistency and shared latent space to capture spacetime-varying motion patterns."
 Radar
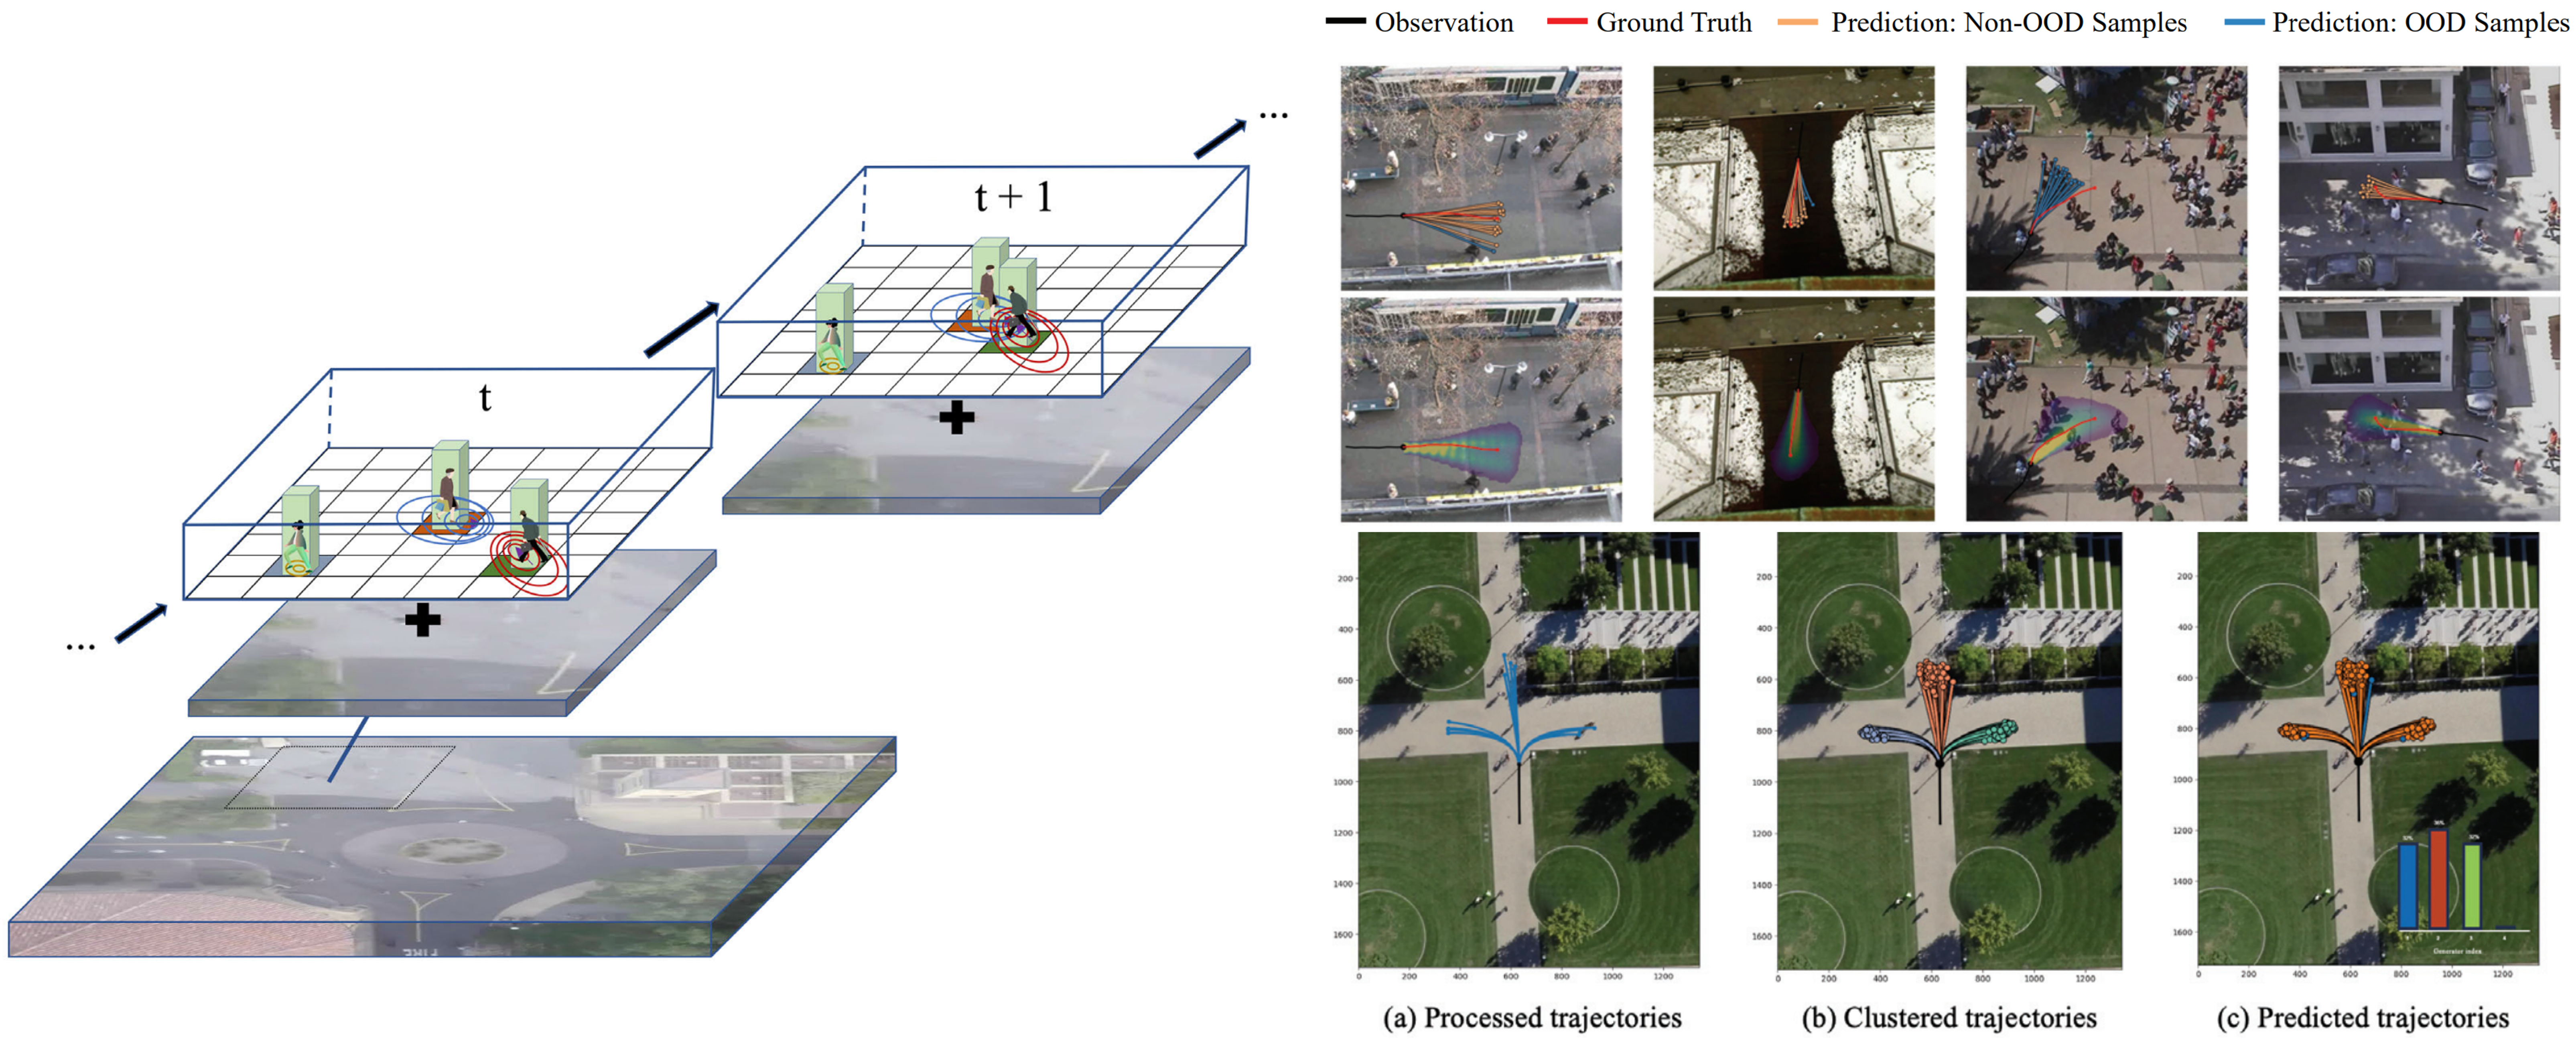
Flexible Multi-generator Model with Fused Spatiotemporal Graph for Trajectory Prediction
International Radar Conference (IRC), 2023. Oral
"A multi-generator trajectory prediction framework using a fused spatiotemporal graph to model complex pedestrian interactions."
 Book
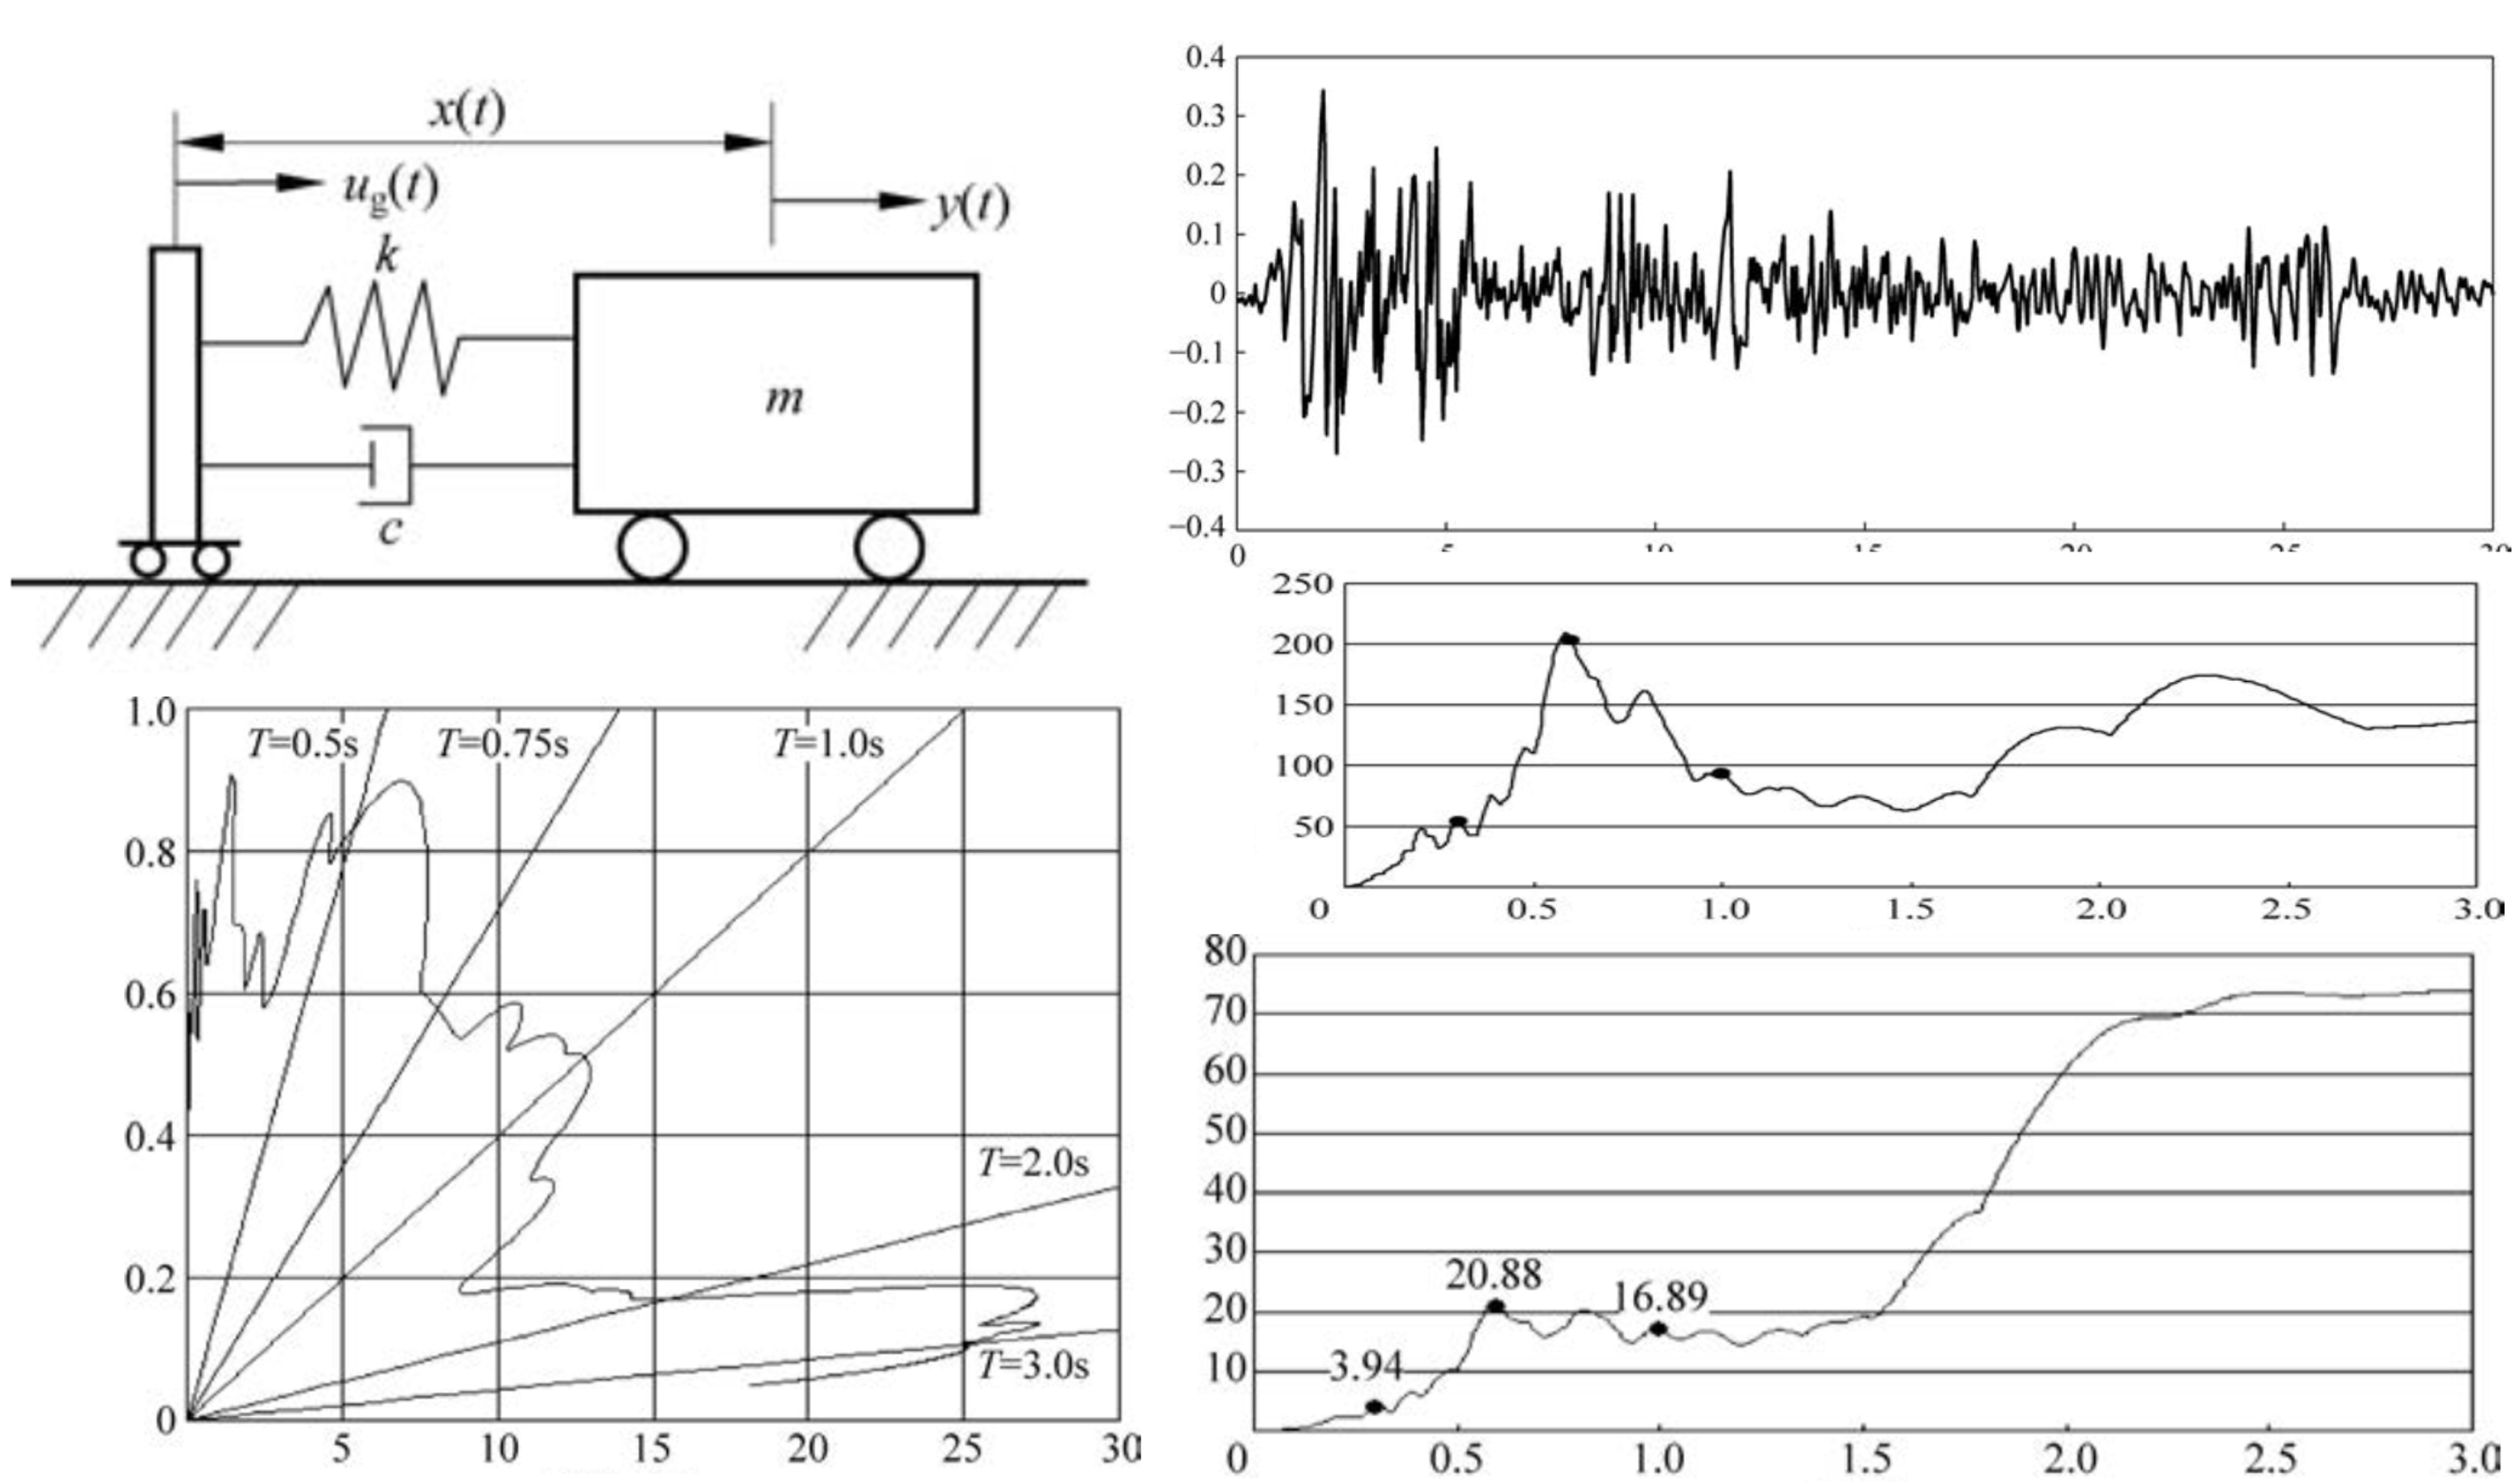
Comprehensive Performance Analysis and Evaluation of Building Construction Throughout Its Lifecycle
Tsinghua University Press, 2022.
"This book presents lifecycle performance analysis for building construction, covering seismic risk, environmental cost, energy consumption, and social cost. It combines engineering evaluation principles with case studies and software-based lifecycle assessment workflows."